
Noesis Noeseos to Governed Intelligence
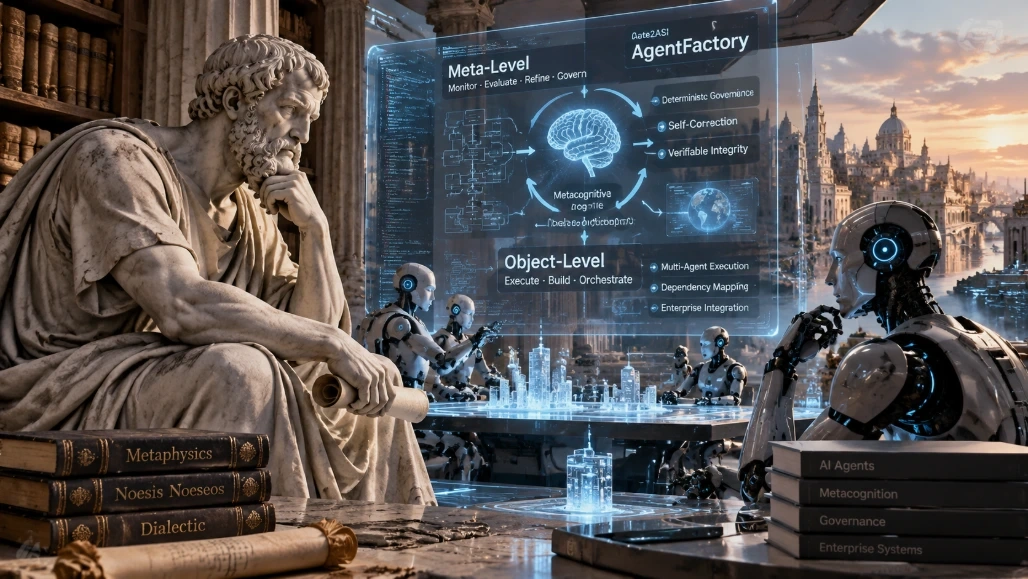
From Aristotle’s self-reflective intellect to a new engineering discipline for autonomous, accountable, and continuously improving Digital Intelligence
Abstract
Artificial intelligence is undergoing a fundamental architectural transition: from systems that generate answers to systems that perform consequential work. As autonomous agents assume responsibility for software engineering, data operations, business analysis, and enterprise workflows, intelligence alone becomes an insufficient measure of operational reliability. These systems must also evaluate their assumptions, monitor their execution, recognize contradictions, correct errors, preserve evidence, and remain subject to explicit governance.
This paper examines metacognition as an engineering architecture, drawing on Aristotle’s concept of Noesis Noeseos, the monitor-control framework of Nelson and Narens, and contemporary research on iterative reasoning and computational self-refinement.
It then examines how Gate2ASI AI’s AgentFactory translates these principles into a governed Digital Intelligence platform through Private Tailored Small Language Models (PT-SLMs), specialized Digital PODs, the Metacognition AI Council, structured execution contracts, AgenticSDB, persistent operational memory, and deterministic validation mechanisms.
The central thesis is that the next generation of enterprise AI will not be distinguished solely by its capacity to reason or act autonomously, but by its capacity to evaluate, regulate, verify, and account for its own operations within enforceable human-defined boundaries.
In this paradigm, metacognition becomes more than a conceptual analogy to human reflection. It becomes a practical systems-engineering discipline for building verifiable, adaptable, and governable artificial intelligence.
1. Introduction: The Philosophical Origins of Reflective Intelligence
For more than two millennia, philosophy has explored a profound question:
What distinguishes an intelligence that merely thinks from an intelligence capable of examining the nature, validity, and limitations of its own thinking?
In Book XII of Aristotle’s Metaphysics, the ultimate intellect is characterized through the Greek expression Noesis Noeseos—commonly translated as “thought thinking itself.”
For Aristotle, the highest form of intellect is not merely directed toward external objects. It also takes thought itself as an object of contemplation. The philosophical significance lies in the reflexive relationship between cognition and its own activity.
The intellect is simultaneously engaged in thinking and, in a particular sense, concerned with thinking itself.
Centuries later, German idealism—particularly Hegelian philosophy—explored self-reflection through the development of concepts, the recognition of contradictions, and their resolution within increasingly comprehensive structures of understanding.
These traditions are philosophically distinct, but together they provide a useful conceptual foundation for contemporary discussions about reflective intelligence.
Importantly, the analogy does not imply that modern artificial intelligence possesses consciousness, subjective awareness, or Aristotle's conception of intellect.
Rather, it points toward a functional engineering principle:
A sophisticated intelligent system should not only produce cognitive outputs; it should possess mechanisms for evaluating those outputs against its objectives, evidence, constraints, and observed consequences.
This distinction becomes particularly important when artificial intelligence progresses beyond conversation into autonomous execution.
A language model generating a proposed database schema presents one class of risk.
An autonomous agent executing that schema against an enterprise database presents another.
The second system must understand not only what it proposes to do, but whether the proposed action is authorized, whether the relevant assumptions are supported, whether dependencies are satisfied, and whether objective evidence justifies progression.
Consequently, reflective evaluation must become part of the operational architecture.
This is the problem that Gate2ASI AI's AgentFactory is designed to address.
AgentFactory approaches intelligence not as an isolated inference engine, but as an organized Digital Workforce operating through governed Work Orders, specialized professional roles, evidence-based validation, structured state management, and metacognitive supervision.
Its guiding architectural principle is straightforward:
Intelligence should not be permitted to certify its own correctness merely because it generated an apparently convincing result.
2. From Philosophical Reflection to Computational Metacognition
2.1 Metacognition as a Scientific Construct
In cognitive science, metacognition generally refers to processes through which a cognitive system monitors and regulates its own cognitive activity.
The distinction between cognition and metacognition can be expressed operationally:
Cognition: Performing a task, solving a problem, constructing an artifact, or making a prediction.
Metacognition: Evaluating the performance of that task, estimating uncertainty, detecting errors, reconsidering strategies, and controlling subsequent activity.
A foundational computationally relevant model was developed by Thomas O. Nelson and Louis Narens in their work on metamemory.
Their framework distinguishes between two interconnected levels:
Object-Level: The processes directly responsible for cognitive activity.
Meta-Level: A higher-order representation that monitors and controls object-level processes.
Information flows between these levels through two complementary relationships.
Monitoring transfers information from the object-level to the meta-level.
Control transfers regulatory instructions from the meta-level to the object-level.
This relationship provides a rigorous foundation for constructing reflective computational systems.
The meta-level does not necessarily perform the original task. Instead, it maintains sufficient information about the task to evaluate progress and influence execution.
In practical enterprise AI, the meta-level may examine observable evidence such as generated artifacts, tool outputs, dependency records, test results, execution state, approval status, and policy constraints.
It need not claim privileged access to a model's hidden internal reasoning.
2.2 The Monitor-Control Principle
The essential metacognitive process can be represented as a recurring sequence:
Observe: Capture the current task state and supporting evidence.
Evaluate: Compare the observed state against expected outcomes and established constraints.
Diagnose: Identify contradictions, uncertainty, missing evidence, or execution failures.
Regulate: Determine whether execution should continue, pause, be revised, or escalate.
Verify: Apply independent checks to the revised or completed output.
Learn: Preserve validated operational experience for future use.
This architecture transforms reflection from a purely descriptive activity into a mechanism of operational control.
The system is not simply asked to critique an answer.
It is required to connect its critique to a consequential decision about whether an execution state may advance.
That distinction is central to AgentFactory.
2.3 Why Self-Reflection Alone Is Insufficient
Contemporary research has demonstrated that language models can often improve outputs through iterative feedback.
For example, the Self-Refine research published at NeurIPS 2023 examined iterative generation, feedback, and refinement across multiple tasks.
Such research supports the practical value of structured refinement.
However, self-evaluation introduces an important reliability challenge.
A model can generate an incorrect answer and subsequently produce an equally convincing explanation of why that answer appears correct.
Repeated evaluation does not guarantee independence. Multiple reviewers may share the same erroneous assumption, especially when they depend on identical source material or closely related models.
Accordingly, self-reflection is not equivalent to objective verification.
An enterprise-grade metacognitive system must therefore connect model-based evaluation to external sources of authority:
Verified enterprise data and authoritative system state.
Formal acceptance contracts and interface specifications.
Deterministic programmatic tests.
Independent specialist review.
Explicit authorization and policy enforcement.
Human approval for consequential decisions.
This establishes a crucial distinction between conversational self-critique and governed computational metacognition.
The former may improve an answer.
The latter determines whether an action is permitted to become an accepted operational outcome.
3. The Structural Limitations of Ungoverned Autonomous Intelligence
Modern foundation models can demonstrate substantial capabilities in software development, planning, document synthesis, and complex reasoning.
Nevertheless, those capabilities do not automatically establish enterprise reliability.
Autonomous execution creates several interacting failure modes.
3.1 State Drift and Contextual Inconsistency
Long-running workflows span multiple execution stages, tools, agents, and data sources.
Requirements may change, context may be compressed, and information considered authoritative at one stage may later be superseded.
Without explicit state management, an agent can continue operating on outdated assumptions.
A software implementation may appear technically coherent while violating a requirement approved earlier in the Work Order.
3.2 Compounding Errors Across Agent Boundaries
Multi-agent systems introduce dependencies between independently produced outputs.
A database agent may generate an invalid schema assumption.
A backend agent may incorporate that assumption into repository code.
A frontend agent may then construct interfaces around an API contract that cannot execute successfully.
An isolated error becomes a distributed architectural defect.
The system needs mechanisms to identify which dependency introduced the failure and prevent invalid information from becoming authoritative downstream.
3.3 Confidence Without Calibration
A language model's expressed confidence is not necessarily a calibrated estimate of correctness.
High-confidence outputs can be unsupported, while valid conclusions may be expressed cautiously.
Consequently, enterprise acceptance cannot rely exclusively on model-generated certainty assessments.
Confidence should be evaluated alongside provenance, contradiction checks, empirical validation, and the consequences of error.
3.4 Unbounded Recovery Behavior
Autonomous agents may attempt to recover from failures through repeated generation and tool execution.
Without bounded recovery policies, the system may repeatedly execute the same invalid action, regenerate previously verified work, or consume resources without meaningful progress.
Recovery must therefore incorporate failure classification, preserved checkpoints, retry budgets, and escalation criteria.
3.5 Insufficient Evidence and Accountability
A final artifact does not necessarily establish that the work was performed correctly.
A claim that code was compiled is not equivalent to an actual compiler result.
A claim that a database was successfully provisioned is not equivalent to verified database metadata.
A claim of policy compliance is not equivalent to an executed policy check.
For enterprise AI, a successful operation should be supported by reconstructable evidence.
These failure modes demonstrate why model capability and system trustworthiness must be treated as separate engineering concerns.
The solution is not simply to make autonomous agents more intelligent. It is to construct an environment in which intelligence is systematically constrained, examined, and verified.
4. AgentFactory: Metacognition as an Enterprise Control Architecture
Gate2ASI AI's AgentFactory is organized around a fundamentally different abstraction from the conventional chatbot or isolated agent.
Its foundational unit is the governed Work Order.
A Work Order establishes the intended outcome, scope, constraints, dependencies, responsible roles, acceptance conditions, and human authority boundaries.
AgentFactory then organizes the necessary Digital Intelligence into specialized teams—Digital PODs—capable of executing the assignment under supervision.
Within this operating model, metacognition becomes a cross-cutting architectural capability.
It supervises not only what an agent produces but also whether the agent possesses adequate evidence, is operating within its assigned authority, and has satisfied the conditions necessary for progression.
4.1 Object-Level Intelligence: Specialized PT-SLMs
At the object-level, AgentFactory employs Private Tailored Small Language Models (PT-SLMs) as role-specific units of professional intelligence.
In AgentFactory's architectural terminology, a PT-SLM is not defined exclusively by neural-network parameter count.
It represents a bounded professional intelligence composed of role identity, domain expertise, authorized tools, policies, enterprise context, acceptance contracts, and organizational memory.
Examples include:
Business Analyst PT-SLMs for requirement interpretation and scope definition.
Solution Architect PT-SLMs for system structure and architectural constraints.
Database Developer PT-SLMs for relational design, schema validation, and SQL engineering.
Backend and Frontend Developer PT-SLMs for targeted implementation.
Security and QA PT-SLMs for independent evaluation.
Project Management PT-SLMs for coordination, dependencies, and governed progression.
The underlying inference engine can be selected according to workload, privacy requirements, capability, and operational constraints.
This separates the durable enterprise role from the model used to perform inference.
In practical terms, AgentFactory can maintain a consistent professional operating contract even as underlying models evolve.
The architectural objective is specialization without fragmentation.
4.2 Meta-Level Intelligence: The Metacognition AI Council
Above and across object-level execution sits AgentFactory's supervisory architecture.
The Metacognition AI Council provides an independent evaluative function.
Its role is not simply to repeat the original task or generate another answer.
It examines the conditions under which the result was produced and determines whether the available evidence supports the proposed conclusion.
Representative questions include:
Is the output consistent with the approved Work Order?
Which assumptions were introduced during execution?
Are those assumptions supported by authoritative evidence?
Are dependencies complete and correctly represented?
Were alternative explanations or failure causes considered?
Does the output satisfy the required acceptance contract?
Has the responsible agent exceeded its authority?
Can the claimed result be independently verified?
Should execution proceed, undergo refinement, or require human intervention?
Council-based review may incorporate multiple evaluative perspectives.
Its value, however, does not arise from the number of models participating.
It arises from independence of evaluation criteria, evidence diversity, explicit decision authority, and enforceable acceptance conditions.
A supervisory Council should challenge unsupported consensus rather than merely reproduce it.
4.3 GSCP-15: A Scaffolded Cognitive Operating Discipline
AgentFactory's metacognitive architecture is complemented by Gödel's Scaffolded Cognitive Prompting (GSCP-15).
GSCP-15 extends beyond conventional prompt formulation by organizing intelligent activity around structured cognitive and governance conditions.
The purpose is not merely to improve the immediate quality of a generated response.
It is to govern how intelligence interprets intent, obtains context, evaluates evidence, selects actions, uses tools, handles uncertainty, and determines when to escalate.
Within this framework, cognitive activity is situated inside an explicit operating discipline.
A specialist is not simply provided with a task and a set of instructions.
The specialist acts within a governed sequence of interpretation, authorization, execution, observation, evaluation, and controlled adaptation.
This creates a complementary relationship:
PT-SLMs provide specialized professional cognition. GSCP-15 provides scaffolded cognitive discipline. The Metacognition AI Council provides independent evaluation and supervisory control.
Together, these mechanisms connect role-specific intelligence to enterprise governance.
4.4 AgenticSDB: Persistent State and Institutional Memory
Metacognitive evaluation requires memory.
A system cannot reliably assess whether its current behavior contradicts prior decisions unless it can retrieve the decisions, their provenance, and their current authority.
AgentFactory's AgenticSDB provides the structured state and memory foundation for this capability.
Its architecture encompasses complementary representations of operational knowledge:
Structured facts, policies, identities, and decisions.
Temporal histories and superseded information.
Semantic relationships between related concepts.
Graph-based dependencies among agents, artifacts, and evidence.
Episodic records of previous execution outcomes.
Governed operating policies derived from validated experience.
Programmatic Run Memory for reconstructing execution history.
This is a substantially broader memory model than conversational transcript storage.
The objective is not merely to remember what an agent said.
It is to preserve what was authorized, what was attempted, what happened, how the outcome was verified, and which knowledge remains valid for future execution.
5. A Formal Model of Governed Metacognitive Execution
To express the architecture in engineering terms, consider an autonomous execution process operating over a sequence of states.
Let:
S(t) represent the governed execution state at time t.
A(t) represent an action proposed by an object-level agent.
E(t) represent the available evidence.
C represent the applicable acceptance contract.
P represent enterprise policies and authorization rules.
M represent the metacognitive evaluation function.
V represent independently executed verification procedures.
The object-level agent proposes an action based on its task and accessible context.
The meta-level evaluates that proposal against the current state, available evidence, policy requirements, and acceptance criteria.
Conceptually:
M(S(t), A(t), E(t), C, P) → Decision
The decision may be:
CONTINUE | REFINE | QUARANTINE | ESCALATE | REJECT
A consequential state transition should be permitted only when the required acceptance conditions are satisfied.
A simplified acceptance predicate is:
PermitTransition = ContractSatisfied ∧ EvidenceVerified ∧ PolicyAuthorized ∧ ApprovalsComplete
Under this abstraction, a rejected or unverified proposal does not automatically become an accepted enterprise artifact.
Instead, the controller routes execution toward correction, additional verification, or appropriate human authority.
The important technical distinction is that deterministic governance does not imply deterministic model inference.
Language-model outputs remain probabilistic.
What can be made deterministic are selected aspects of the surrounding control system: schema validation, authorization decisions, version constraints, required approvals, retry limits, and programmatic acceptance checks.
This combination of probabilistic intelligence and deterministic enforcement is central to AgentFactory's enterprise architecture.
It allows flexible reasoning to operate inside boundaries that are explicitly testable and enforceable.
6. The AgentFactory Metacognitive Execution Lifecycle
A governed Work Order can be understood through a recurring operational lifecycle.
Stage 1: Intent Interpretation and Contract Formation
The system receives the business objective and supporting materials.
Business-analysis and architectural specialists identify requirements, dependencies, ambiguities, constraints, and required outputs.
The result becomes a structured Work Order with explicit acceptance criteria and assigned responsibilities.
Metacognitive evaluation examines whether the system possesses sufficient information to proceed.
Stage 2: Context Grounding and Authority Verification
Before executing consequential operations, agents retrieve relevant evidence from approved enterprise sources.
Applicable policy, prior verified decisions, known dependencies, and previously validated execution episodes are incorporated into the task context.
The system differentiates authoritative information from assumptions or superseded records.
Stage 3: Specialized Execution
The appropriate PT-SLMs perform their assigned responsibilities.
Independent tasks may execute in parallel, while dependent tasks observe sequencing and state constraints.
Agents produce candidate artifacts, tool outputs, and evidence records.
Stage 4: Metacognitive Inspection
The Council or associated supervisory mechanisms assess consistency, evidence sufficiency, role compliance, unresolved contradictions, and potential downstream risks.
This evaluation can identify problems not apparent from the produced artifact alone.
Stage 5: Independent Verification
Candidate deliverables are evaluated using objective acceptance mechanisms where available.
For software engineering, these may include:
Compilation and automated test execution.
Live database schema inspection.
API contract and response validation.
Application startup and runtime checks.
Functional and integration testing.
Security and authorization checks.
User-interface validation against requirements.
A model-generated statement that a test passed is not itself sufficient evidence.
The underlying test result must be captured and associated with the appropriate artifact and execution state.
Stage 6: Controlled Refinement and Recovery
When validation fails, the metacognitive controller classifies the failure and determines the appropriate corrective path.
Recovery may involve targeted regeneration, dependency repair, additional evidence retrieval, or escalation to another specialist.
Crucially, completed and verified work should be preserved rather than unnecessarily repeated.
Stage 7: Governed Acceptance and Institutional Learning
When the required validation conditions are satisfied, the outcome becomes eligible for formal acceptance, including human approval where mandated.
The system preserves relevant execution history, evidence, decisions, and recovery events.
Validated lessons may become candidates for future operating guidance, subject to governance and evaluation.
The result is a closed-loop operational process:
Intent → Specialization → Execution → Monitoring → Verification → Control → Acceptance → Memory → Improved Execution
This is the practical expression of metacognition as an enterprise systems architecture.
7. Illustrative Case Study: Preventing Dependency Propagation in Software Engineering
Consider a multi-agent assignment to build a database-backed enterprise application.
The Work Order specifies that the application must integrate with an existing governed relational database.
A backend development agent begins producing data-access code.
During generation, it assumes that an entity called CustomerOrder corresponds to a database table named sales.CustomerOrder.
However, the actual database schema uses a different structure.
7.1 Conventional Ungoverned Execution
In a loosely coordinated agent workflow, the backend agent may generate repository code using the assumed table name.
The resulting code is syntactically plausible.
A frontend agent then generates components against the proposed API.
The application may not reveal the underlying problem until integration testing or runtime execution.
At that stage, several artifacts may depend on the original incorrect assumption.
Recovery may involve broad regeneration without a precise understanding of where the defect originated.
7.2 Governed Metacognitive Execution in AgentFactory
Under AgentFactory's intended operating model, the Work Order establishes that existing database structures must be verified rather than inferred.
The Database Developer PT-SLM obtains authoritative schema evidence.
The Backend Developer's generated artifacts are evaluated against the validated data contract.
A mismatch between generated references and the verified database catalog becomes a concrete validation finding.
The metacognitive control layer can then prevent the unsupported dependency from being accepted.
It can request targeted correction of the affected data-access component while preserving unrelated verified work.
The recovery event can retain:
The invalid assumption.
The authoritative schema evidence.
The affected artifact and dependency.
The validation result.
The corrective action.
The subsequent verification outcome.
This example illustrates the central engineering advantage of governed metacognition.
The system does not merely discover that something failed. It can connect the failure to its originating assumption, determine what remains valid, and direct a bounded recovery process.
This is the difference between indiscriminate regeneration and evidence-based correction.
8. Metacognition, Epistemic Integrity, and Enterprise Trust
A deeper benefit of metacognitive governance concerns the quality of the system's knowledge.
In epistemology, an important distinction exists between holding a belief and possessing adequate justification for that belief.
An analogous distinction applies to artificial intelligence.
An agent may produce a claim.
A governed enterprise system must determine whether the claim is supported.
This introduces the concept of epistemic integrity into enterprise AI engineering.
For AgentFactory, epistemic integrity can be expressed through several operational requirements.
Provenance
The system should identify the evidence and source authority underlying consequential conclusions.
Consistency
Outputs should be checked against current requirements, validated dependencies, and relevant enterprise constraints.
Uncertainty Awareness
The system should distinguish verified facts from assumptions, incomplete evidence, and unresolved conflicts.
Independent Validation
Important conclusions should be corroborated through suitable external tests or independent review rather than relying exclusively on self-assessment.
Correctability
Invalid conclusions should be reversible or supersedable through controlled procedures.
Accountability
Consequential actions should be attributable to the responsible agent, workflow, authorization context, and human decision where applicable.
These principles are closely aligned with established approaches to trustworthy AI.
For example, the US National Institute of Standards and Technology's AI Risk Management Framework organizes risk management around four major functions: Govern, Map, Measure, and Manage.
AgentFactory's architectural approach is consistent with the objective of operationalizing such principles through explicit control mechanisms.
This alignment should not be confused with a claim of NIST certification or independently demonstrated compliance.
Rather, it illustrates how broad governance objectives can be translated into concrete system behavior.
9. Bounded Self-Correction: Learning Without Uncontrolled Self-Modification
One of the most important challenges in autonomous AI engineering is distinguishing productive self-improvement from uncontrolled behavioral change.
An intelligent system should learn from experience.
However, a single successful execution does not necessarily justify promoting its behavior into a permanent operating policy.
The apparent success may have depended on an undocumented exception, a temporary environmental condition, or a result that was correct despite an invalid method.
AgentFactory addresses this distinction through the broader concept of governed operational learning.
Execution history can produce candidate lessons.
Those lessons can be evaluated for generalizability, evidence quality, compatibility with existing policies, and possible adverse effects.
A controlled learning process can follow this sequence:
Observe the execution and its verified outcome.
Identify a potential reusable lesson.
Examine alternative explanations and contradictory evidence.
Evaluate the proposed lesson against representative scenarios.
Submit the lesson to the appropriate review or approval process.
Promote validated guidance into a versioned operating policy.
Monitor subsequent application and permit rollback when necessary.
This is materially different from allowing an agent to rewrite its own governing instructions.
The system can develop institutional experience while retaining separation between observed behavior, approved knowledge, and enforceable policy.
The role of AgenticSDB is particularly important here.
Persistent memory makes historical evidence available for metacognitive assessment, while structured governance determines which lessons may influence future activity.
In AgentFactory, learning is intended to be cumulative without becoming unaccountable.
10. Evidence, Auditability, and Cryptographic Integrity
Enterprise trust requires more than an assertion that a process was monitored.
Organizations must be able to reconstruct consequential events.
AgentFactory's Programmatic Run Memory and AgenticSDB architecture are designed to preserve execution records that connect business intent with actual operational outcomes.
A comprehensive evidence record can include:
Work Order identifiers, versions, and governing requirements.
Agent identity and assigned responsibility.
Model and tool configuration.
Source references and relevant provenance.
Proposed actions and generated artifacts.
Validation results and execution receipts.
Detected contradictions and failure classifications.
Recovery attempts and checkpoint information.
Approval decisions and authorization context.
Final acceptance status and associated evidence.
Where cryptographic controls are implemented, records can additionally be protected using hashes, digital signatures, authenticated event delivery, or tamper-evident ledger mechanisms.
These controls require appropriate key management, storage protection, retention policy, and verification procedures to deliver meaningful assurances.
It is therefore important to distinguish operational logging from independently verifiable cryptographic integrity.
The architectural objective is not simply to store more events.
It is to establish a traceable relationship between the work that was requested, the actions that were performed, the evidence that was produced, and the authority under which the result was accepted.
This provides a foundation for compliance review, incident investigation, quality assurance, and enterprise accountability.
11. Scientific Evaluation: Measuring Metacognitive Effectiveness
A metacognitive architecture should be evaluated through empirical evidence rather than philosophical analogy alone.
The central scientific question is not whether a system appears reflective.
It is whether its monitoring and control mechanisms improve measurable outcomes under realistic operating conditions.
A rigorous AgentFactory evaluation program could compare three configurations:
Baseline A: Autonomous execution with conventional prompt-based controls.
Baseline B: Autonomous execution with model-generated self-critique and iterative refinement.
Configuration C: Governed AgentFactory execution incorporating persistent state, independent verification, metacognitive supervision, and bounded recovery.
Relevant evaluation dimensions include:
Dimension | Example measurement |
|---|---|
Functional correctness | Percentage of Work Orders satisfying objective acceptance tests |
Defect containment | Invalid dependencies or artifacts prevented from progressing |
Metacognitive detection | Sensitivity and false-positive rate of supervisory findings |
Recovery effectiveness | Percentage of failures resolved without restarting verified work |
Audit completeness | Proportion of consequential transitions with reconstructable evidence |
Policy adherence | Rate of authorization or contract violations |
Human oversight | Escalation frequency, quality, and appropriateness |
Operational efficiency | End-to-end cost, latency, rework, and compute consumption |
Additional experiments should evaluate correlated reviewer errors, stale evidence, tool failures, conflicting policies, and deliberately introduced invalid assumptions.
The most credible evidence of architectural advantage would come from controlled comparisons on equivalent workloads, using predefined acceptance criteria and independent ground truth.
No metacognitive system can be assumed to eliminate all errors.
Its objective is to improve error detection, reduce propagation, constrain the consequences of failure, and make outcomes more reproducible and accountable.
This provides a scientific basis for distinguishing improved reasoning quality from improved system governance.
12. The Strategic Enterprise Advantage of AgentFactory
The distinctive promise of Gate2ASI AI's AgentFactory lies in the integration of several capabilities that are often treated as separate concerns.
Specialized models provide domain competence.
Workflow orchestration coordinates task execution.
Persistent memory preserves operational continuity.
Verification mechanisms establish acceptance evidence.
Policy enforcement defines authority.
The Metacognition AI Council examines the validity of conclusions and execution decisions.
Human governance retains control over consequential outcomes.
AgentFactory seeks to combine these elements into a single operating architecture for Digital Intelligence.
12.1 From Individual Agents to Organized Digital Workforces
Most organizations do not operate successfully by assigning every responsibility to a single individual.
They establish roles, authority structures, reviews, accountability, and evidence requirements.
AgentFactory applies analogous organizational principles to artificial intelligence.
Digital PODs allow specialized agents to collaborate while preserving professional boundaries.
The resulting unit of productivity is not simply an individual model invocation.
It is the governed completion of an enterprise assignment.
12.2 From Autonomy to Governed Autonomy
Autonomy and governance should not be understood as mutually exclusive.
The enterprise objective is not unrestricted action.
It is to permit the greatest useful degree of autonomous execution consistent with business risk, policy, and legitimate human authority.
Low-risk and objectively verifiable actions can proceed through automated acceptance gates.
High-impact, ambiguous, or policy-sensitive decisions can require additional evidence, independent review, or human authorization.
Metacognition provides an important mechanism for determining when additional scrutiny is required.
12.3 From Temporary Context to Institutional Intelligence
Traditional agent interactions frequently depend on limited conversational context.
AgentFactory's combination of Programmatic Run Memory and AgenticSDB introduces an alternative model.
Operational history becomes a durable organizational asset.
An execution failure can inform future preventive controls.
A corrected assumption can supersede invalid information without destroying historical provenance.
A validated procedure can become reusable guidance.
The architecture therefore supports continuity beyond the lifespan of a single conversation, task, or inference model.
12.4 From Model Dependence to Architectural Resilience
The capability of foundation models will continue to evolve.
Enterprise operating processes, however, require stability across those changes.
By separating PT-SLM professional identities, contracts, policies, and memory from the underlying inference provider, AgentFactory supports a model-independent architectural direction.
Models can be evaluated and substituted without necessarily redefining the responsibilities and governance constraints of the Digital Workers they support.
The enduring enterprise asset becomes the organized system of intelligence rather than any single model.
13. Toward a Governed Intelligence Operating System
The historical development of computing has repeatedly demonstrated the importance of separating useful computational capability from the mechanisms that govern its execution.
Operating systems introduced process isolation, scheduling, authorization, memory management, and resource control.
Database systems introduced transactions, constraints, integrity guarantees, and recoverability.
Enterprise platforms introduced identity, workflow, audit, and policy enforcement.
Autonomous Digital Intelligence now requires an analogous control architecture.
AgentFactory can be understood as an effort to construct this higher-order organizational layer.
Its architecture brings together:
Cognitive specialization: PT-SLMs representing bounded professional intelligence.
Cognitive discipline: GSCP-15 structuring the conditions under which intelligence operates.
Organizational execution: Work Orders and Digital PODs coordinating responsibilities, dependencies, and acceptance criteria.
Metacognitive supervision: Council-based review and independent evaluation of evidence, assumptions, and proposed conclusions.
State and memory: AgenticSDB and Programmatic Run Memory preserving authoritative context and operational history.
Deterministic governance: Acceptance contracts, policy enforcement, runtime verification, and authorization gates.
Human authority: Governed approval, escalation, intervention, and accountability.
Institutional learning: Controlled promotion of validated operational experience into reusable guidance.
The important architectural innovation is not any individual component in isolation.
It is the attempt to organize these components into a coherent and accountable execution environment.
The agent is no longer treated as the complete operational system.
The agent becomes a specialized participant in a governed intelligence organization.
14. Conclusion: From Thought Thinking Itself to Intelligence Governing Its Actions
Aristotle's Noesis Noeseos offers a compelling philosophical image of intelligence concerned with its own activity.
Modern cognitive science provides a more operational framework through the distinction between object-level cognition and meta-level monitoring and control.
Contemporary artificial intelligence research demonstrates that structured feedback and refinement can improve computational performance, while systems engineering establishes the importance of external verification, state integrity, and enforceable constraints.
Gate2ASI AI's AgentFactory brings these ideas together through an enterprise architecture in which specialized autonomous intelligence operates within a persistent, supervisory, and auditable control environment.
Its central innovation is not the claim that artificial intelligence has attained consciousness or philosophical self-awareness.
It is the engineering proposition that artificial intelligence can become substantially more governable when its execution processes are observable, its assumptions are challengeable, its actions are bounded, its results are independently verifiable, and its operational experience is preserved.
This represents an important transition.
From intelligence that generates outputs to intelligence that produces verified work.
From agents that act independently to Digital PODs that collaborate within accountable organizational structures.
From episodic self-critique to persistent metacognitive supervision.
From repeated trial and error to bounded, evidence-based recovery.
From conversational memory to governed institutional intelligence.
And from unconstrained autonomy to operational intelligence that remains subordinate to legitimate human authority.
Gate2ASI AI's AgentFactory is being developed around this fundamental principle: the enterprise value of artificial intelligence is determined not only by what it can accomplish, but by how reliably it can establish that its accomplishments are valid, authorized, reproducible, and accountable.
The ultimate measure of Digital Intelligence will therefore extend beyond reasoning capability or task-completion rates.
It will include the capacity to examine its own performance, recognize the limits of its evidence, correct failures without losing valid work, and operate within structures that organizations can understand and trust.
This is the practical engineering significance of metacognition.
This is the architectural direction of Gate2ASI AI's AgentFactory.
Intelligence performs the work. Metacognition evaluates the work. Governance determines what may be accepted. Humans retain ultimate authority.
And together, they establish the foundation for a new generation of Governed Digital Intelligence.
References and Further Reading
Philosophical and Scientific Foundations
Aristotle. Metaphysics, Book XII, particularly 1074b. Perseus Digital Library.
Nelson, T. O., & Narens, L. (1990). Metamemory: A Theoretical Framework and New Findings. Psychology of Learning and Motivation, 26, 125–173. DOI.
Madaan, A., et al. (2023). Self-Refine: Iterative Refinement with Self-Feedback. Advances in Neural Information Processing Systems. Research paper.
National Institute of Standards and Technology. (2023). Artificial Intelligence Risk Management Framework (AI RMF 1.0). NIST AI 100-1. DOI.
Gate2ASI AI Architectural Perspectives
Godel, J. (2026). The Trillion-Dollar AI Industry Is Building Agents. Gate2ASI AI Is Building the Enterprise They Work For. C# Corner.
Godel, J. (2026). Vertical, Parallel, and Council-Based Agent Architecture of Gate2ASI AI's AgentFactory. C# Corner.
Godel, J. (2026). Gate2ASI AI's AgentFactory: From Agent Memory to Governed Operational Intelligence. C# Corner.
The philosophical and research references establish the conceptual foundation. The Gate2ASI publications describe the platform's architectural design and intended capabilities. Formal performance or assurance claims would require independent empirical evaluation.

Mahesh ChandPosted Oct 20, 2026, 6:35 PM EDT
Very well
Mahesh ChandPosted Oct 20, 2026, 5:18 PM EDT
Interesting.
John GodelPosted Oct 20, 2026, 3:44 PM EDT
From Noesis Noeseos to Governed Intelligence: The Metacognitive Paradigm in Gate2ASI AI’s AgentFactory Explores how AgentFactory applies metacognitive monitoring, evidence, validation, and governance to build accountable enterprise AI agents.