Loading
Topic
Apache Iceberg
13 posts about Apache Iceberg by 8 contributors.
Know Apache Iceberg? Share what you know with developers who are learning it.
+ Follow Apache IcebergBe the first to follow this
- Articles
- 13
- Contributors
- 8
Everything about Apache Iceberg
- Article · Google Cloud
Querying Apache Iceberg Tables Directly From AlloyDB
Learn how to query Apache Iceberg data from AlloyDB, design read-oriented analytical workloads, and plan for performance, permissions, and data freshness.
- Article · Google Cloud
Querying Apache Iceberg Tables Directly From AlloyDB
Learn how to query Apache Iceberg data from AlloyDB, including workload design, SQL query patterns, permissions, performance, and data freshness considerations.
- Article · Big Data
Changing Apache Iceberg Partitioning Without Rewriting Your Entire Data Pipeline
Learn how Apache Iceberg partition evolution changes a table's partition strategy for new writes without immediately rewriting historical data files.
- Article · Google Cloud
Build Delta Lake Imports With Dataflow Job Builder
Learn how to use Google Cloud Dataflow Job Builder to import Delta Lake tables from Cloud Storage into Apache Iceberg Lakehouse tables, including prerequisites and schema considerations.
- Article · Google Cloud
Spanner Becomes a Runtime Catalog for Apache Iceberg
Learn how Google Cloud's Lakehouse runtime catalog uses Spanner and the Apache Iceberg REST Catalog API to provide consistent, scalable metadata management for shared lakehouse tables.
- Article · Google Cloud
Spanner Becomes a Runtime Catalog for Apache Iceberg
Learn how Google Cloud Spanner can serve as a transactional runtime catalog for Apache Iceberg tables while data and metadata files remain in object storage.
- Article · Software Architecture/Engineering
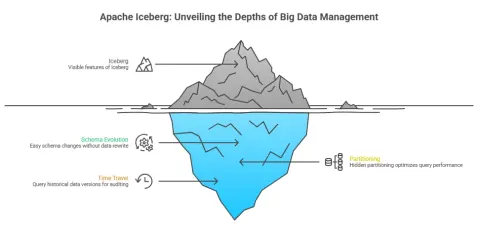
Apache Iceberg Explained: Modern Data Lake Architecture for Developers
Learn Apache Iceberg architecture, ACID transactions, schema evolution, time travel, and query optimization for building scalable modern data lakes.
- Article · Databases & DBA
Apache Iceberg Explained: The Foundation of Modern Data Lakehouses
Apache Iceberg: The open table format revolutionizing data lakehouses with ACID transactions, schema evolution, and time travel for massive analytics.