Loading
Topic
Big Data Processing
4 posts about Big Data Processing by 4 contributors.
Know Big Data Processing? Share what you know with developers who are learning it.
+ Follow Big Data ProcessingBe the first to follow this
- Articles
- 4
- Contributors
- 4
Articles about Big Data Processing
- Article · Design Patterns & Practices
Apache Flink Explained: Real-Time Stream Processing for Modern Applications
Learn how Apache Flink enables real-time stream processing, event-driven applications, stateful computations, and scalable analytics for modern data platforms.
- Article · Microsoft Fabric
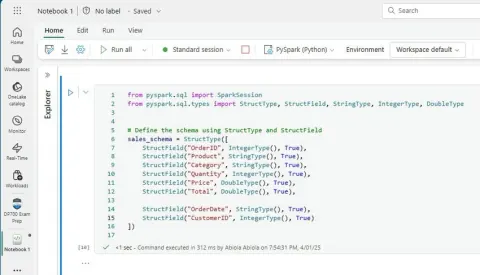
Viewing the Content of Spark DataFrames in Fabric Notebook
Discover techniques to preview, filter, and analyze large datasets using Apache Spark. Whether you're working with PySpark or big data processing, enhance your workflow with efficient DataFrame visualization.
- Article · Big Data
Getting Started With Apache Spark
In Big Data, Hadoop components such as Hive (SQL construct), Pig ( Scripting construct), and MapReduce (Java programming) are used to perform all the data transformations and aggregation.
- Article · Azure
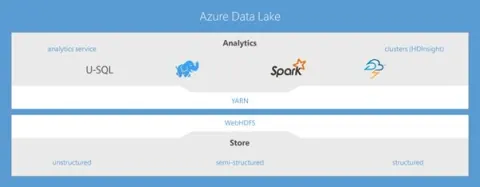
Introducing U-SQL- Make Big Data Processing Easy
In this article you will learn the introduction of U-SQL that makes Big Data Processing easy.