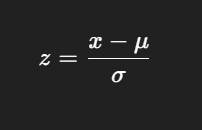Loading
Topic
Data Preprocessing
8 posts about Data Preprocessing by 7 contributors.
Know Data Preprocessing? Share what you know with developers who are learning it.
+ Follow Data PreprocessingBe the first to follow this
- Articles
- 8
- Contributors
- 7
Everything about Data Preprocessing
- Article · Machine Learning
Feature Engineering in Machine Learning: Techniques and Examples
Learn Feature Engineering in Machine Learning with practical examples. Explore feature creation, transformation, selection, encoding, scaling, and best practices.
- Article · Machine Learning
How to Perform Feature Scaling in Machine Learning Step by Step
Master feature scaling in ML! Learn step-by-step techniques (Min-Max, Standardization) to boost model accuracy, speed up training, and avoid common pitfalls.
- Article · Python
How to Clean and Preprocess Data in Python Using Pandas Step by Step
Master data cleaning and preprocessing in Python using Pandas. This step-by-step guide covers handling missing data, duplicates, outliers, and more for accurate analysis.
- Article · AI
What is Machine Learning Pipeline?
Automate ML model building, training, & deployment with a Machine Learning Pipeline. Streamline workflow, enhance data management, & boost efficiency. Learn how!
- Article · Machine Learning
What is the role of StandardScaler in ML preprocessing?
Learn how this crucial preprocessing technique from scikit-learn standardizes your data by removing the mean and scaling to unit variance, preventing feature dominance and accelerating model convergence. Discover when and how to use StandardScaler for optimal ML performance, especially with algorithms like SVM, KNN, and Neural Networks.
- Article · Machine Learning
What Is Feature Engineering
Feature engineering is the process of transforming raw data into meaningful inputs for machine learning models. It boosts model performance by creating, selecting, and refining features.
- Article · Machine Learning
Wrangling Outliers and Noise in Your Data
This comprehensive guide explores the nuances between outliers and noise in data analysis. It delves into identification techniques and handling strategies, showcasing practical examples for effective data cleaning and analysis.
- Article · Data Science
Mastering Data Mining Techniques
Data mining uncovers hidden patterns in vast data reserves, guiding decision-making. Key preprocessing steps ensure data quality, from collection to transformation, optimizing insights for impactful analysis and decision-making.