Loading
Topic
LLM testing
6 posts about LLM testing by 4 contributors.
Know LLM testing? Share what you know with developers who are learning it.
+ Follow LLM testingBe the first to follow this
- Articles
- 6
- Contributors
- 4
Articles about LLM testing
- Article · LLMs
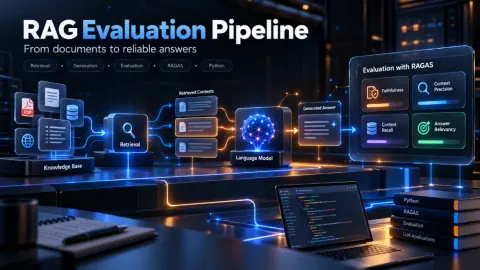
How to Build a RAG Evaluation Pipeline With Python: Metrics, RAGAS, and Testing
Learn how to evaluate a Python RAG pipeline with RAGAS using faithfulness, context precision, context recall, and answer relevancy metrics.
- Article · Software Testing
Testing AI Agents with Synthetic Enterprise Documents
Test AI agents with synthetic enterprise documents to evaluate extraction accuracy, grounding, hallucinations, edge cases, document variations, and system reliability under controlled conditions.
- Article · AI
Building Agent Evaluation Gates for Tool-Calling Regression Tests
Build automated evaluation gates for AI agents to detect tool-calling regressions when prompts, schemas, models, or agent workflows change across development and deployment.
- Article · Software Testing
AI Quality Assurance: Testing Strategies for LLM-Powered Applications
Master AI quality assurance for LLM apps. Explore testing strategies for accuracy, relevance, security, and reliability.
- Article · Prompt Engineering
Exploring Promptfoo: Testing and Evaluating LLM Prompts Like a Pro
Promptfoo is an open-source tool revolutionizing LLM prompt engineering. It enables systematic testing, evaluation, and benchmarking of prompts, ensuring reliable, unbiased, and cost-effective results. Automate regression testing, compare models (GPT-4, Llama 3), and integrate human evaluation for subjective outputs.
- Article · Prompt Engineering
How Do You Evaluate Prompt Effectiveness?
Evaluating prompt effectiveness is key to successful prompt engineering. Learn the metrics, methods, and tools to measure how well prompts guide AI models in producing accurate and reliable results.