Loading
Topic
Q-Learning
6 posts about Q-Learning by 3 contributors.
Know Q-Learning? Share what you know with developers who are learning it.
+ Follow Q-LearningBe the first to follow this
- Articles
- 6
- Contributors
- 3
Articles about Q-Learning
- Article · AI Agents
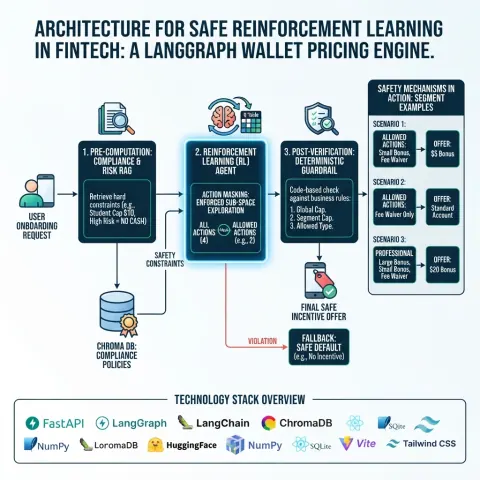
Safe Exploration: Guarding RL-Based Pricing in Digital Wallet Onboarding
Unsafe exploration is not an RL problem it is an architecture problem. By combining RAG-driven constraint retrieval, action masking, and deterministic guardrail nodes within a LangGraph workflow, we create a system where the RL agent can learn and optimize within a provably safe boundary. For digital wallet onboarding, this means better conversion rates without regulatory nightmares.
- Article · AI Agents
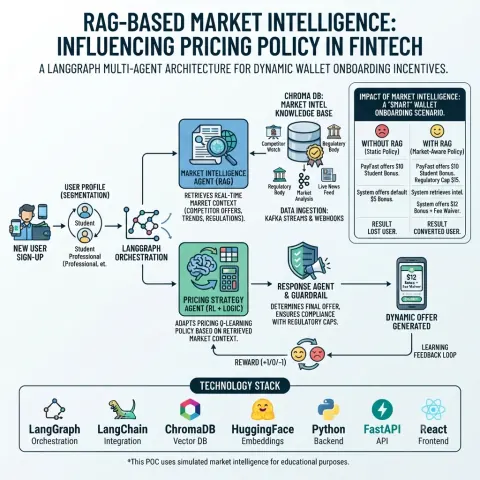
Context is King: How RAG-Based Market Intelligence Drives Dynamic Wallet Pricing
RAG-based market intelligence transforms a pricing engine from a reactive calculator into a proactive strategist. By grounding decisions in real-time external data, we ensure that wallet creation incentives are not just mathematically optimal, but competitively viable. This POC illustrates the power of combining LangGraph, RAG, and RL to build intelligent, context-aware financial systems.
- Article · AI Agents
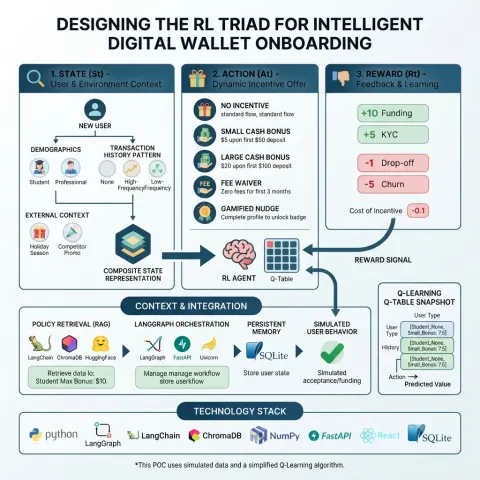
Designing the RL Loop: State, Action, and Reward in a Digital Wallet Onboarding Engine
Designing the State, Action, and Reward is the most critical step in building an RL-powered pricing or onboarding engine. By defining these clearly and wrapping them in a LangGraph multi-agent architecture, we can create systems that are not only intelligent but also compliant and context-aware. This POC demonstrates how to move from static marketing to dynamic, learning-driven user engagement.
- Article · AI Agents
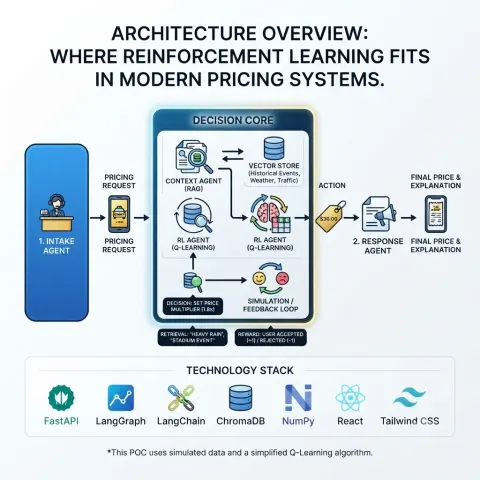
Orchestrating Intelligence: Integrating Reinforcement Learning into a Dynamic Pricing Engine with LangGraph
Reinforcement Learning fits into the architecture as the adaptive decision-maker. By wrapping it in a LangGraph workflow, we can combine its learning capabilities with the contextual awareness of RAG and the structural integrity of Multi-Agent Systems. This POC demonstrates how to build a pricing engine that doesn't just react to data, but learns from every transaction to optimize future revenue.
- Article · AI
What is Reinforcement Learning?
Reinforcement Learning (RL) is a powerful branch of AI where agents learn optimal behavior by interacting with an environment and receiving feedback. This article explains how RL works, its key components, algorithms, real-world use cases, and its significance in building intelligent systems.
- Article · AI
Deep Reinforcement Learning
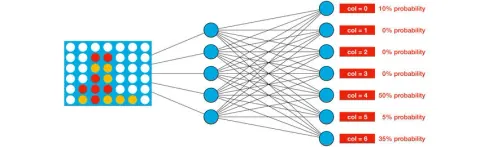
Learn how to train a game-playing agent using reinforcement learning and neural networks—no heuristics needed. This tutorial covers rewards, strategies, and building intelligent agents through self-play.