Loading
Topic
RAG evaluation
8 posts about RAG evaluation by 5 contributors.
Know RAG evaluation? Share what you know with developers who are learning it.
+ Follow RAG evaluationBe the first to follow this
- Articles
- 8
- Contributors
- 5
Articles about RAG evaluation
- Article · LLMs
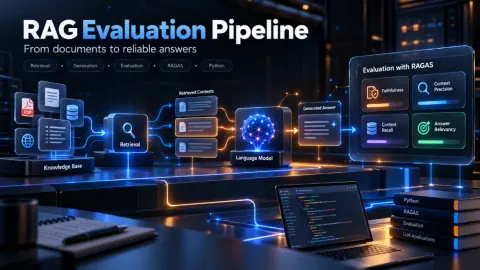
How to Build a RAG Evaluation Pipeline With Python: Metrics, RAGAS, and Testing
Learn how to evaluate a Python RAG pipeline with RAGAS using faithfulness, context precision, context recall, and answer relevancy metrics.
- Article · AI Agents
Evaluating RAG Systems: A Multi-Agent LangGraph Framework for Comprehensive Quality Assessment
Build a multi-agent LangGraph framework to evaluate RAG systems using context precision, recall, faithfulness, answer relevancy, and correctness metrics.
- Article · AI Agents
RAGAS and G-Eval: Building an Enterprise-Grade RAG Evaluation System with Multi-Agent LangGraph
Build a multi-agent LangGraph system that combines RAGAS diagnostic metrics and G-Eval LLM-as-a-judge scoring to evaluate RAG quality in production.
- Article · AI Agents
Diagnosing RAG Failure Modes: A Multi-Agent LangGraph Diagnostician
Build a multi-agent LangGraph workflow that audits RAG retrieval, classifies failure modes, identifies root causes, and recommends targeted fixes using persistent failure memory.
- Article · AI
How to Test Your AI App After a GPT-6 Model Update
Learn how to test an AI app after a GPT-6 model update using regression tests, structured outputs, tool calls, RAG, security checks, and production validation.
- Article · Langchain
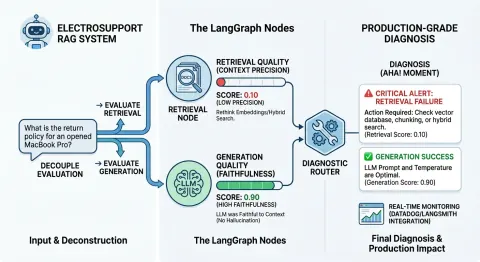
Measuring Retrieval vs. Generation Quality Independently using LangGraph
Master RAG evaluation by decoupling retrieval & generation with LangGraph. Pinpoint bottlenecks for production-grade AI.
- Article · Prompt Engineering
AI Evaluation Frameworks for .NET Applications: Measuring Accuracy and Reliability
Master AI evaluation for .NET apps. Measure accuracy, reliability, safety, performance, and cost for trustworthy, scalable AI solutions.
- Article · LLMs
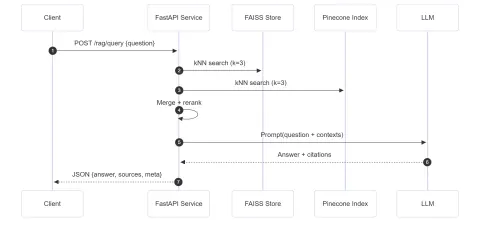
Advanced RAG in Python with FastAPI – Multi-Source Retrieval and Evaluation
Build, evaluate, and deploy a production-ready Retrieval-Augmented Generation (RAG) system in Python using FAISS, Pinecone, LangChain, and FastAPI. Includes code, Dockerfile, diagrams, and an evaluation workflow.