Loading
Topic
self-attention
4 posts about self-attention by 3 contributors.
Know self-attention? Share what you know with developers who are learning it.
+ Follow self-attentionBe the first to follow this
- Articles
- 4
- Contributors
- 3
Everything about self-attention
- Article · AI
Schrödinger's AI Part 5: Transformers in AI
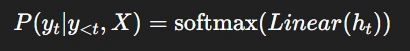
Demystifying Transformers in AI! Forget robots, this guide breaks down the genius model architecture that powers AI like ChatGPT. Learn about self-attention, positional encoding, encoder-decoder structure, and how transformers predict the next word using vectors and probabilities. Understand the magic behind AI text generation!
- Article · LLMs
Context Window in Large Language Models (LLMs)
Explore the context window in LLMs: its impact on performance, limitations due to self-attention, and trade-offs in RAG systems. Learn how it shapes LLM behavior.
- Article · Machine Learning
Transformers vs RNNs: Key Differences Explained
Explore the core differences between RNNs and Transformers, two pivotal architectures in NLP and deep learning. Discover why Transformers, with their parallel processing and self-attention, have surpassed RNNs in performance, scalability, and versatility, becoming the foundation for modern AI models like BERT and GPT.
- Article · LLMs
The Transformer Model Architecture in LLM
Unlock the power of Large Language Models (LLMs) by understanding the Transformer architecture! This article breaks down the core components: embeddings, encoder, and decoder. Learn how Transformers process text, create contextual understanding, and generate human-quality responses. Explore different Transformer types like BERT, GPT, T5, and BART, and their unique applications in NLP.