6 posts about transformer architecture by 5 contributors.
Know transformer architecture? Share what you know with developers who are learning it.
Why are LLMs costly? This in depth guide explains training cost, inference cost, GPU infrastructure, attention scaling, KV cache memory, architecture internals, and why some models are more expensive than others.

Explore Large Language Models (LLMs): how they work, their uses in AI, and key considerations for enterprise deployment in cloud environments.
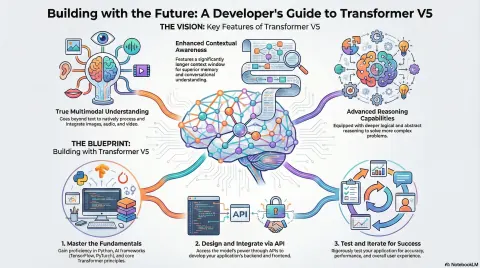
A deep technical guide explaining what Transformer v5 introduces and how developers use its APIs, architecture changes, and performance improvements in production systems.
Explains how LLM context length affects reasoning, accuracy, coherence, latency, and cost, and how context engineering techniques such as RAG and summarization manage long inputs.
Dive into the technical depths of Large Language Models (LLMs). Explore tokenization, transformer architecture, training pipelines, instruction tuning, inference optimization, quantization, and long-context methods. Learn practical engineering details for building, deploying, and evaluating LLM systems, including tool use, security, and serving architectures. Discover tips for optimizing performance and ensuring reliability.
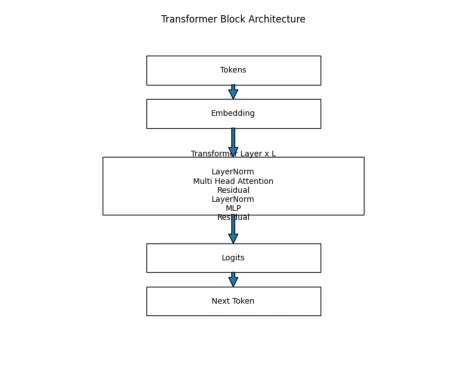
Unlock the power of Large Language Models (LLMs) by understanding the Transformer architecture! This article breaks down the core components: embeddings, encoder, and decoder. Learn how Transformers process text, create contextual understanding, and generate human-quality responses. Explore different Transformer types like BERT, GPT, T5, and BART, and their unique applications in NLP.
DevSocialUpcoming · 3rd editionAI Agents ConferenceNov 23–27, 2026Live onlineMembers only16days leftRegisterPublish an article in this category and earn +1,000 SHARP when it is approved.
Write an article