5 posts about transformer models by 4 contributors.
Know transformer models? Share what you know with developers who are learning it.
Learn how KV cache-aware routing reuses cached transformer attention states to reduce repeated prompt processing, lower latency, and improve GPU efficiency in LLM inference.

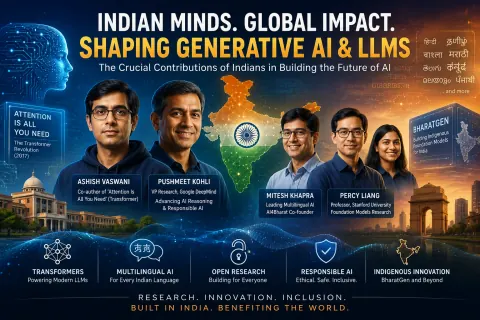
Discover what crucial contributions Indian researchers made to Generative AI and Large Language Models and how their work helped shape modern AI systems, multilingual models, and responsible AI research.
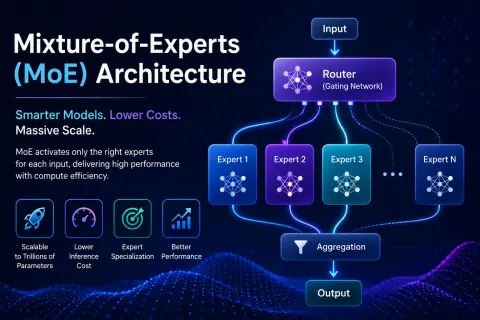
Learn what Mixture-of-Experts (MoE) architecture is and how it helps large AI models scale efficiently. Explore how MoE works, its benefits, challenges, use cases, and implementation strategies.
Learn how Large Language Models (LLMs) work in simple, natural language. Understand tokenization, embeddings, transformers, attention, training, inference, hallucinations, applications, prompt engineering, and the future of AI.
DevSocialUpcoming · 3rd editionAI Agents ConferenceNov 23–27, 2026Live onlineMembers only17days leftRegisterPublish an article in this category and earn +1,000 SHARP when it is approved.
Write an article