Loading
Topic
Transformer
3 posts about Transformer by 3 contributors.
Know Transformer? Share what you know with developers who are learning it.
+ Follow TransformerBe the first to follow this
- Articles
- 2
- Videos
- 1
- Contributors
- 3
Articles about Transformer
- Article · AI
Understanding Transformers in Large Language Models (LLMs): Internal Components and Their Roles
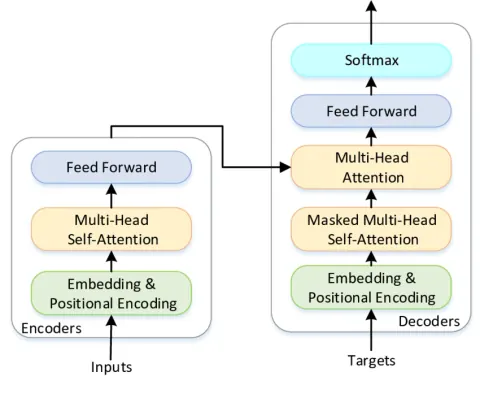
This article explores the Transformer architecture, the backbone of modern LLMs like GPT and BERT, detailing key components such as self-attention, feedforward layers, positional encoding, and training mechanisms.