Loading
Topic
vision language action model
2 posts about vision language action model by 2 contributors.
Know vision language action model? Share what you know with developers who are learning it.
+ Follow vision language action modelBe the first to follow this
- Articles
- 2
- Contributors
- 2
Everything about vision language action model
- Article · AI
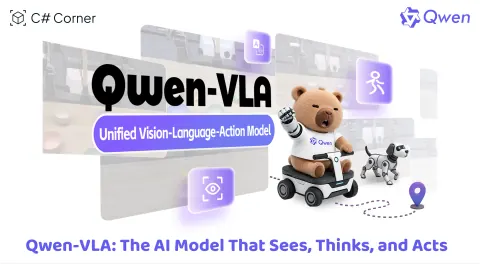
Qwen-VLA: The AI Model That Sees, Thinks, and Acts
Alibaba's Qwen-VLA is a single AI model that controls robots across tasks and bodies. Here's what makes it different — and why it matters for the future of robotics.
- Article · Generative AI
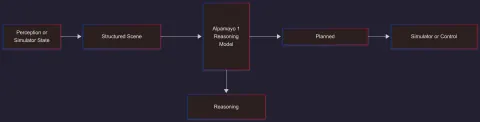
How to Use Alpamayo 1 by Nvidia: What It Is and How to Apply It
Learn what Alpamayo 1 is and how to use Nvidia’s vision-language-action model step by step, from setup and inference to simulation, reasoning analysis, and integration workflows.