Loading
Topic
autoscaling
14 posts about autoscaling by 9 contributors.
Know autoscaling? Share what you know with developers who are learning it.
+ Follow autoscalingBe the first to follow this
- Articles
- 14
- Contributors
- 9
Articles about autoscaling
- Article · Google Cloud
Setting Cloud Run Spending Limits Before Your Application Goes Live
Learn how Cloud Run billing works and how to use maximum instances, resource settings, and budget alerts to reduce unexpected Google Cloud costs.
- Article · Google Cloud
How to Scale Temporal Workers on Google Cloud Run Without Running Them All Day
Learn how to run and scale Temporal Workers on Google Cloud Run using services or worker pools, with guidance on autoscaling, idle costs, and scale-to-zero limitations.
- Article · Cloud
What is Autoscaling in Cloud Computing?
Learn how autoscaling in cloud computing dynamically adjusts resources based on demand, optimizing performance, cost, and reliability. Essential for modern apps!
- Article · Cloud
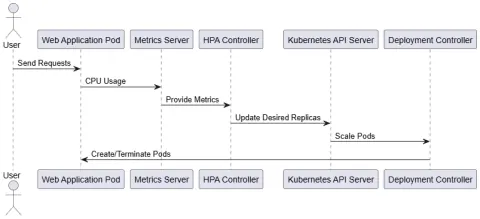
CPU Based Scaling Architecture
Dynamically scale Kubernetes pods with CPU-based Horizontal Pod Autoscaling (HPA). Ensure optimal performance, cost efficiency, and resilience in enterprise environments.
- Article · LLMs
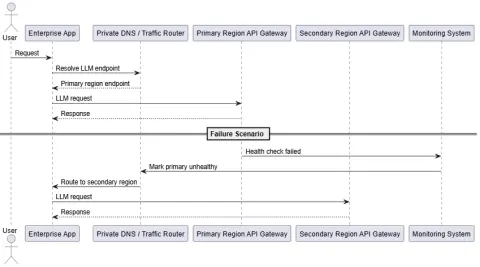
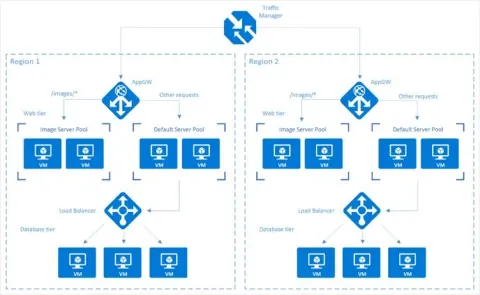
Enterprise-Grade Private LLM Deployment Architecture: Secure, Autoscaling, Multi-Region, and Internet-Isolated
Ensure LLM resilience with a secure, autoscaling, multi-region architecture. Achieve near-zero downtime, regulatory compliance, and enterprise-grade availability.
- Article · Azure
AZ-900 Series 2: Kickstart Your Cloud Career
Discover the key benefits of using cloud services like Azure, including high availability, scalability, reliability, security, and ease of management.