Loading
Abiola David's contributions
- Article · Azure
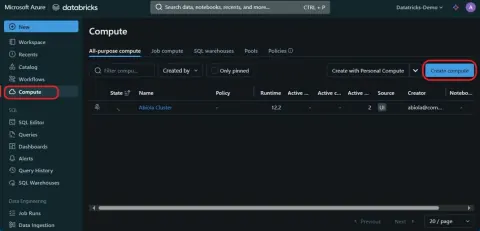
Azure Databricks Cluster
Azure Databricks simplifies big data analytics and machine learning with managed Spark clusters on Azure. It scales dynamically, optimizing resource usage and costs. Integrated with Azure services, it supports high-performance data processing.
- Video · Azure
Azure Data Fatory: Direct Data Integration to Fabric Lakehouse Delta Table
This video shows how to leverage Azure Data Factory to directly integrate data from Azure Data Lake Storage Gen2 to Fabric Lakehouse Delta Table
- Article · Microsoft Fabric
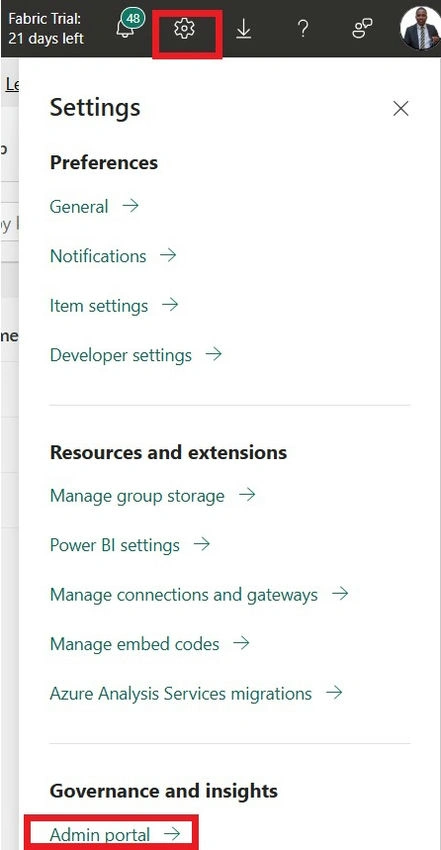
Enabling GitHub Integration in Microsoft Fabric
Learn how to enable GitHub integration in the Microsoft Fabric Admin Portal, configure delegate settings, and connect a GitHub account for workspace Git integration and CI/CD workflows.
- Video · Azure
Azure Databricks | JSON to PySpark Data Transformation
In this video, I demonstated how to leverage Azure Databricks to read JSON data, create Spark DataFrame and perform filtering.
- Video · Microsoft Fabric
Introduction to Spark Scala in Fabric Notebook for Analysis
This video shows dives into Scala as an important languages supported in the Fabric Notebook. Covered in this vide is how to read delta table from Lakehouse in the Fabric Notebook leveraging the scala language.
- Video · Azure
Recursive Traversal in Azure Synapse to Fabric Lakehouse
In this data engineering video, I demonstrated how to recursively traverse multiple CSV files in Azure Data Lake Storage Gen2 using Azure Synapse Notebook and write the data to OneLake in Fabric Lakehouse.
- Video · Microsoft Fabric
Implementing Practical CI/CD in Fabric Notebook Leveraging Azure DevOps
In this end to end video, I covered how to Implement Practical CI/CD in Microsoft Fabric Leveraring Azure DevOps.
- Video · Azure
Read, Combine and Analyse ADLS Gen2 CSV files using Azure Synapse Spark SQL
This video shows how to use Azure Synapse Analytics to read, combine, and analyze multiple CSV files residents in ADLS Gen2 using Spark SQL.
- Video · Microsoft Fabric
ETL: FOLDER Excel Files to Fabric Warehouse using Dataflow Gen2
In this video, I demonstrated how to use the Dataflow Gen2 to connect and append to multiple Excel files and published to the Fabric Warehouse for analysis.
- Video · Microsoft Fabric
Implementing Fabric Data Pipeline Triggers & Schedule
This video shows how to implement Fabric Data Pipeline Triggers & Schedule to seamlessly and continuously ingest CSV files from Azure Blog Storage to Fabric Warehouse without intervention!
- Video · Azure
Azure Data Factory Git Integration using Azure DevOps
This video shows how to integrate Azure Data Factory to git using Azure DevOps.
- Video · Microsoft Fabric
Cross-Workspace Lakehouses Data Transfer using Pipeline Dynamic Content
This video shows how to transfer data between lakehouses from one workspace to another using data pipeline dynamic content.
- Article · Microsoft Fabric
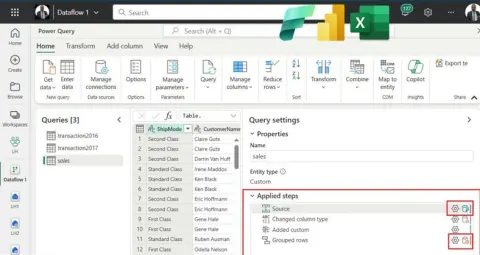
Query Folding in Fabric Dataflow Gen2 (Power Query Online)
Understanding Query Folding in Fabric Dataflow Gen2 (Power Query Online)" explores the concept of query folding within Microsoft's advanced data integration tool. Learn how query folding optimizes data transformation processes, enhances performance, and streamlines ETL tasks in Power Query Online.
- Video · Azure
Azure Data Factory: Implementation of Blog Event Trigger for Data Movement
This video shows how to implement blog event trigger in the azure data factory to perform data movement from source to destination.
- Video · Microsoft Fabric
SQL Server Database Tables to Azure SQL using Fabric Data Pipeline
In this Data engineering video, I demonstrate how to Move SQL Server Database Tables to Azure SQL using Fabric Data Pipeline.
- Blog · Microsoft Fabric
Azure Connections in Microsoft Fabric Admin Portal
Discover seamless Azure integration in the Microsoft Fabric Admin Portal. Effortlessly manage cloud connections, network configurations, and infrastructure deployments. Simplify your workflow with intuitive tools for Azure connectivity and administration.
- Video · Azure
Azure Data Factory to Ingest Data From ADLS Gen 2 to Azure Cosmos DB
This video shows how to use Azure Data Factory Data Pipeline to Ingest Data from ADLS Gen 2 to Azure Cosmos DB.
- Video · Microsoft Fabric
Orchestrate BigQuery Data to Fabric Lakehouse using Data Pipeline
This video shows how to Orchestrate BigQuery Data to Fabric Lakehouse using Data Pipeline for analysis in Power BI.
- Video · Azure
Azure Data Factory to Copy Data From GCS to ADLS Gen 2
In this video, we continue in our data engineering videos on how to use Azure Data Factory to ETL data from Google Cloud Storage account to Azure Data Lake Storage Gen2.
- Video · Microsoft Fabric
Fabric Lakehouse Shortcut to Google Cloud Platform Storage
In this Data Engineering video, I walked you through how to create GCP Cloud Storage, upload file into the bucket, create fabric lakehouse and shortcut to the GCP data.
- Video · Microsoft Fabric
Migrate 34m Records from SQL Server to Warehouse using Fabric Data Pipeline Scheduler
In this end-to-end Data Engineering and Analytics project, I walked you through how to migrate 34m of records from on-prems SQL Server to Fabric Data Warehouse using Fabric Data Pipeline.
- Video · Microsoft Fabric
Create Azure ADLS Gen 2 and Fabric Lakehouse Shortcut for Analysis
This video shows how to create Azure ADLS Gen 2, create container, upload files and create a shortcut in Microsoft Fabric Lakehouse for downstream analytics.
- Video · Azure
Ingest Data into Azure SQL Database using SSMS
This video shows how to ingest data into Azure SQL Database using SQL Server Management Studio.
- Video · Microsoft Fabric
Mirroring Snowflake Database in Fabric Warehouse
In this video, I walk you through how to get started with Snowflake Database, create warehouse, database, tables and records and mirrored the database in Fabric Database for downstream analytics. If you like the video, share with your friends and connections and give it a thumps up!
- Article · Microsoft Fabric
Fabric Lakehouse to Snowflake: Seamless Data Integration Pipeline
Explore seamless data integration from Fabric Lakehouse to Snowflake Database using a robust data pipeline. This process involves extracting, transforming, and loading data efficiently, ensuring smooth migration and synchronization between the two platforms.