Loading
Measuring Token Cost Optimization Strategies in Production LLM Applications
Learn how to measure and reduce token usage in production LLM applications using prompt optimization, context management, caching, response limits, and monitoring.
Cost Benchmarking Vector Databases for Enterprise RAG Workloads
Benchmark vector databases for enterprise RAG workloads. Optimize costs by evaluating storage, query performance, and operational overhead.
Feature Flags in ASP.NET Core 11: Safe Feature Rollouts and Progressive Deployment
Master feature flags in ASP.NET Core 11 for safe rollouts, progressive deployment, and instant rollbacks. Reduce risk and enhance CI/CD.
An Enterprise AML Investigation System with Built-In Defenses
Discover an enterprise AML investigation system with built-in defenses against 14 LLM failure modes in financial reasoning.
Building an AI Coding Assistant in ASP.NET Core Using MCP Servers
Build an AI coding assistant in ASP.NET Core using MCP servers to access project files, APIs, and tools for enhanced development workflows.
Feature Flags in .NET: Safe Deployments Without Risk
Master .NET feature flags for safe deployments. Learn to implement, manage, and remove them for risk-free rollouts and A/B testing.
Local AI in .NET MAUI: Running On-Device Models with ONNX Runtime
Unlock Local AI in .NET MAUI! Run ONNX models on-device for faster, private, offline AI experiences across platforms.
How to Deploy Open-Source LLMs on Kubernetes for Production Workloads
Deploy open-source LLMs on Kubernetes for production. Learn architecture, best practices, scaling, and cost optimization for AI workloads.
How to Build an AI Coding Assistant with ASP.NET Core and Local LLMs
Build an AI coding assistant with ASP.NET Core and local LLMs for enhanced privacy, security, and cost control in your development workflow.
Enterprise-Grade Privacy in GenAI: PII Anonymization & Differential Privacy in Multi-Agent RAG
Secure GenAI with PII anonymization & differential privacy in multi-agent RAG. Enterprise-grade privacy for regulated industries.
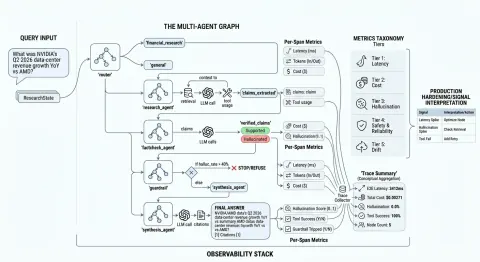
Monitoring LLM Applications in Production
Monitor LLM apps in production with a multi-dimensional observability stack: latency, cost, hallucination, safety, tools, and drift.
AI Observability Explained: Monitoring LLMs, Agents, and RAG Applications
Understand AI Observability: Monitor LLMs, agents, and RAG for better performance, reduced costs, and increased trust.
How to Build Local-First AI Applications Using ONNX Runtime and .NET
Build private, fast, offline AI apps with ONNX Runtime & .NET. Run models locally for enhanced privacy, reduced latency, and lower costs.
AI Cost Optimization Strategies for Production LLM Applications
Master AI cost optimization for production LLMs. Strategies for model routing, prompt reduction, caching, RAG, and monitoring.
Retrieval-Augmented Generation vs Fine-Tuning: Which Approach Works Best?
RAG vs. Fine-Tuning: Understand LLM approaches for domain-specific AI. Learn which works best for your organization's knowledge needs.
Grafana Alloy Explained: The Future of Telemetry Collection
Grafana Alloy unifies telemetry collection for metrics, logs, and traces, simplifying observability in modern, cloud-native systems.
Google Launches AI Inference “LiteRT.js“
Google's LiteRT.js brings fast, private, and cost-effective AI inference to web browsers using local hardware acceleration.
How Vector Search Powers Modern AI Applications and RAG Systems
Unlock AI's potential with vector search! Discover how it powers modern applications, RAG, and semantic understanding beyond keywords.
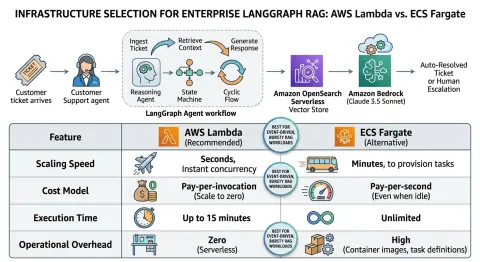
Why AWS Lambda is the Superior Compute Engine for Enterprise LangGraph RAG
Discover why AWS Lambda excels over ECS Fargate for enterprise LangGraph RAG, offering instant scaling and cost efficiency for AI workloads.
Combining LangGraph and RAG for Enterprise Compliance
Building an AI agent for a regulated industry is an exercise in managing the tension between LLM flexibility and regulatory rigidity.
Implementing Local LLM Inference in .NET Applications Using ONNX Runtime
Unlock local LLM inference in .NET with ONNX Runtime for faster, private, and cost-effective AI applications. Learn integration & best practices.
Building AI-Powered Infrastructure Drift Detection Systems with .NET
Build AI-powered infrastructure drift detection with .NET, Terraform, Azure, and OpenAI. Enhance security, compliance, and operational excellence.
AI-Powered Infrastructure Drift Detection with Azure and .NET
Detect infrastructure drift in Azure using AI and .NET. Enhance security, compliance, and operational efficiency with intelligent monitoring.
Diagnosing and Fixing Poor Retrieval Relevance in Enterprise RAG with LangGraph
Fix enterprise RAG retrieval relevance with LangGraph. Overcome chunking, semantic gaps, poor queries, and metadata issues for accurate AI answers.
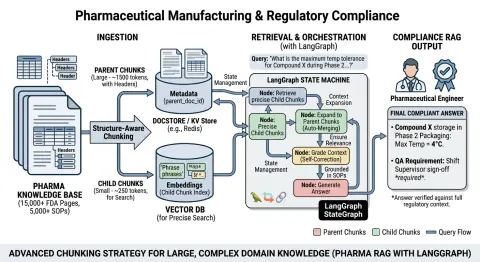
Chunking Strategies for Enterprise RAG
Master enterprise RAG with advanced chunking strategies. Learn structure-aware and parent-child chunking for enhanced accuracy and context retention.