Loading
AI Response Evaluation Pipelines: Measuring Quality Before Production Deployment
Ensure AI quality before production with response evaluation pipelines. Measure accuracy, relevance, safety, and compliance for trustworthy enterprise AI.
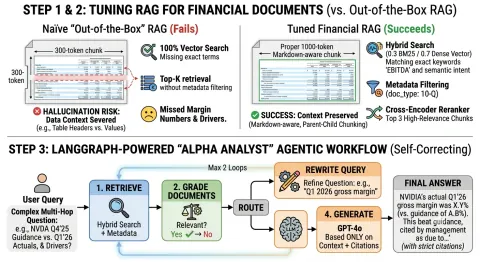
Tuning Chunking, Retrieval, and LangGraph for Institutional-Grade AI
Unlock institutional-grade AI for finance. Tune chunking, hybrid search, and LangGraph for accurate, hallucination-free RAG.
AI Response Quality Scoring: Measuring LLM Output in Production
Measure LLM output quality in production with AI response scoring. Ensure accuracy, relevance, and safety for enterprise AI.
Hybrid RAG with LangGraph: Vector, Keyword & Metadata Retrieval in Action
Master hybrid RAG with LangGraph: Combine vector, keyword, and metadata retrieval for production-ready, auditable AI answers.
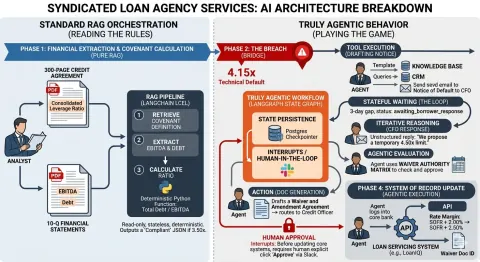
Dissecting RAG vs. Agentic Workflows in Syndicated Loan Operations
When a group of banks lends $500M to a corporation, one bank acts as the "Agent." The Agent is responsible for the administrative plumbing: collecting quarterly financials from the borrower, calculating covenant compliance, distributing funds, and managing exceptions. It is a notoriously document-heavy, highly regulated, and deeply manual process.
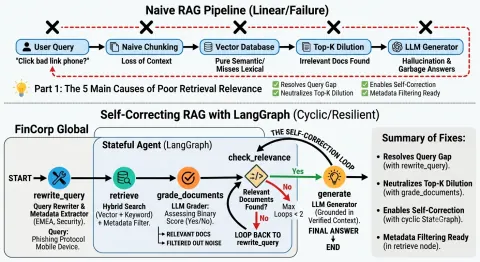
Diagnosing and Fixing Poor Retrieval Relevance in Enterprise RAG with LangGraph
Fix enterprise RAG retrieval relevance with LangGraph. Learn to diagnose and solve common issues like chunking, semantic gaps, and query formulation.
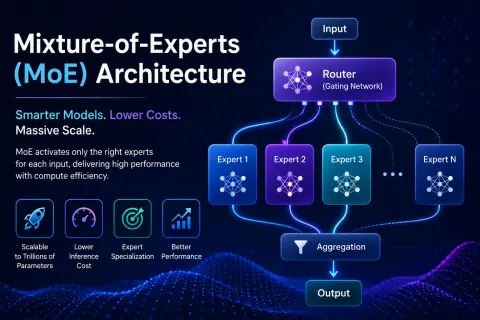
What Is Mixture-of-Experts (MoE) Architecture
Learn what Mixture-of-Experts (MoE) architecture is and how it helps large AI models scale efficiently. Explore how MoE works, its benefits, challenges, use cases, and implementation strategies.
AI Token Optimization Strategies: Reducing Costs Without Sacrificing Accuracy
Reduce AI token costs without sacrificing accuracy. Explore strategies like prompt optimization, caching, and model selection for efficient LLM integration.
Prompt Caching vs Semantic Caching: Performance Optimization Strategies for Enterprise AI Applications
Optimize enterprise AI performance with prompt and semantic caching. Reduce costs, boost speed, and enhance scalability for LLM applications.
Practical AI FinOps: Managing LLM Costs in Production Applications
Master LLM costs in production AI with AI FinOps. Optimize spending, boost performance, and ensure sustainable AI solutions.
Semantic Chunking Strategies for High-Performance RAG Applications
Unlock RAG performance with semantic chunking! Learn strategies to divide content by meaning, not just tokens, for better retrieval and AI responses.
AI Model Routing: Selecting the Right LLM for Every Request
Optimize AI costs & performance by routing requests to the right LLM. Discover strategies for efficient model selection.
How to Implement Semantic Caching in Production AI Applications
Optimize AI apps with semantic caching. Reduce costs, boost speed, and improve scalability by understanding user intent, not just exact wording.
AI Incident Response: Debugging Production Failures in LLM Applications
Master AI incident response for LLM apps. Learn to debug production failures, monitor performance, and ensure reliability with .NET.
How to Build Conversational Knowledge Platforms with AI Search
Unlock organizational knowledge with AI search. Build conversational platforms for natural language Q&A, boosting productivity and efficiency.
Schema-Driven AI Applications: Using Structured Data for Better LLM Responses
Unlock reliable AI with schema-driven applications. Use structured data for predictable LLM responses, easier integration, and robust automation.
Feature Flags for AI Applications: Safe Deployment Strategies in .NET
Safely deploy AI in .NET with feature flags. Control rollouts, A/B test models, manage costs, and ensure governance for AI innovations.
Local AI Inference in .NET: Running Models on Windows Without Cloud APIs
Run AI models locally on Windows with .NET. Explore ONNX Runtime, Ollama, and hardware acceleration for private, fast, and cost-effective AI.
Implementing Semantic Caching in AI Applications to Reduce LLM Costs
Reduce LLM costs with semantic caching. Reuse AI responses for similar queries, lowering expenses and latency in AI apps.
Understanding Hybrid Search Architecture in AI-Powered Applications
Hybrid search combines keyword and vector search for AI apps, improving accuracy and user experience. Essential for RAG.
Why AI Search Is Replacing Traditional Search Faster Than Expected
AI search is rapidly evolving, offering faster, conversational answers and transforming how we find information. Learn how it's impacting SEO and the future of search.
Why AI Agents Are Replacing Traditional Software and What Developers Should Learn Next
AI agents are transforming software! Learn why they're replacing traditional methods, boosting productivity, and the essential skills developers need to thrive.